



SpeechifyAI is a research lab advancing speech synthesis, voice cloning, and emotional expression. Its flagship model, Simba 3.2, is ranked #1 on Artificial Analysis TTS leaderboard, offering sub-100ms latency and low cost. The platform provides a single API for streaming, voice cloning, emotion control, and multilingual synthesis across 30+ locales.
Best AI Voice Cloning Tools (2026)
Compare AI voice cloning tools that recreate a real voice from a short sample for narration, dubbing, multilingual text-to-speech, and voice preservation.
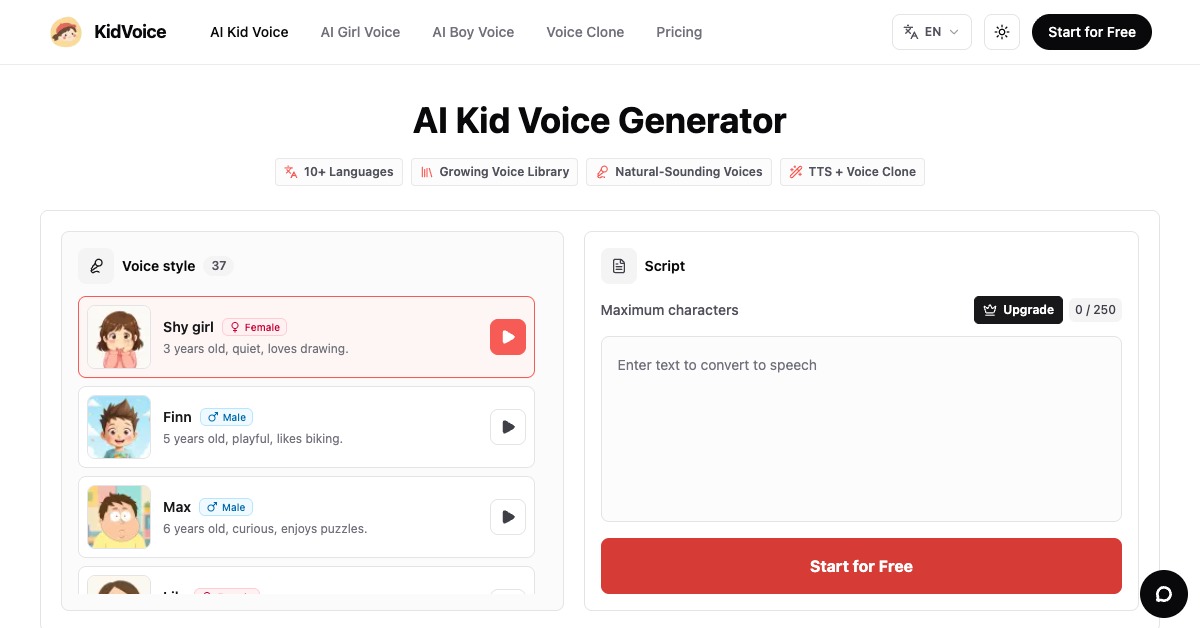
Our advanced voice generator creates authentic and engaging children's voices for all your creative projects.
Related categories
What is AI voice cloning?
AI voice cloning creates a synthetic copy of a specific person's voice from a short audio sample, then makes that voice read any text you type. Modern systems capture timbre, accent, and speaking style, and some clone a voice from seconds of audio (zero-shot) rather than hours of recording. The result powers narration, dubbing, and personal voice assistants.
Key features of voice cloning tools
- Clone a voice from seconds of sample audio
- Text-to-speech playback in the cloned voice
- Cross-language cloning that keeps the original voice
- Emotion, pace, and emphasis controls
- Real-time voice conversion and voice changer mode
- API and SDK for apps and pipelines
Who uses AI voice cloning?
01
Content creators
Narrate videos, podcasts, and audiobooks without re-recording every time a script changes.
02
Localization and dubbing
Dub videos into other languages while keeping the original speaker's own voice.
03
Accessibility and voice preservation
Preserve a personal voice before medical loss, or restore it for everyday communication.
04
Developers and product teams
Add branded, consistent narration to apps, games, and phone systems through an API.
How AI voice cloning works
The system encodes a voice sample into a compact 'voice print' that captures its unique characteristics. A text-to-speech model then generates new speech conditioned on that voice print, so any words come out in the cloned voice. Zero-shot models do this from a few seconds, while higher-fidelity clones are trained on more of your recordings.