



Clideo is a browser-based video editing platform with over 30 online tools for cutting, merging, compressing, converting formats, and adding subtitles to videos. No software installation required — works directly in the browser.
Best Text to Speech AI Tools (2026)
Compare text-to-speech AI for natural voiceover, video narration, audiobooks, voice cloning, multi-language voices, and free plans.


ElevenLabs is a voice AI platform for creating lifelike speech, voice cloning, and building voice agents. It offers APIs and SDKs for developers to integrate voice capabilities into applications.
Speechify is a text-to-speech platform that reads documents, PDFs, web pages, and books aloud using natural AI voices—available as a web app, browser extension, and mobile app with 55M+ users.

Fish Audio is an AI voice platform offering studio-grade text-to-speech and voice cloning. It supports 2,000,000+ community voices across 8 languages, with real-time streaming, emotion control, and a developer API — built for creators, developers, and production teams.

NaturalReader is a text-to-speech application that converts text, PDFs, and web pages into natural-sounding audio using AI voices—available online, as a mobile app, and with commercial licensing.


Udio is an AI music generation platform that creates full songs with vocals from text prompts. It supports dozens of genres, lyrics editing, remixing, and commercial licensing on paid plans.
Vocloner is a free instant voice cloning tool. Upload a short voice sample and Vocloner creates a TTS-ready voice model usable for creators, UGC, and audiobooks.
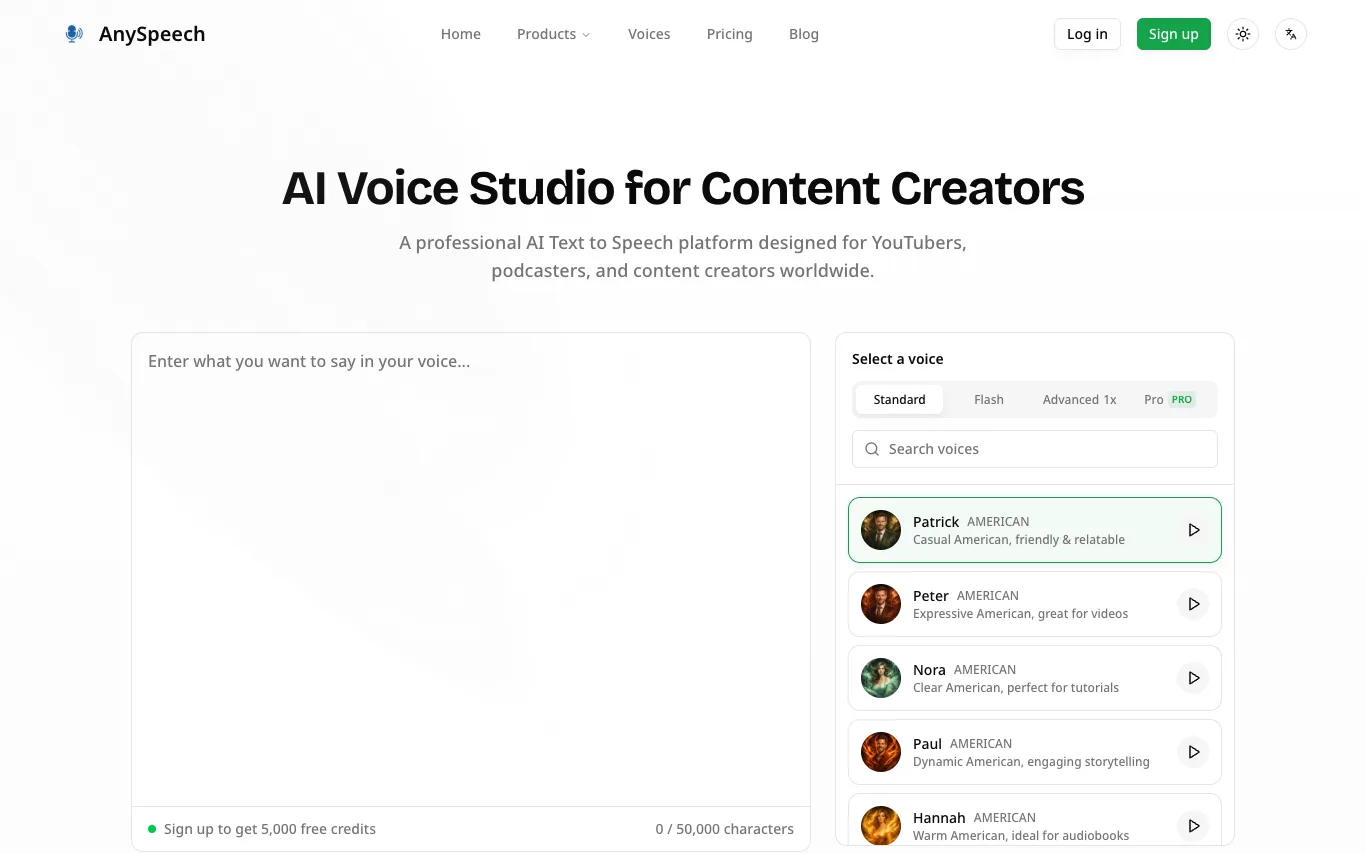

AnySpeech is a professional AI text-to-speech platform that transforms text into natural-sounding speech. It offers over 100 realistic voices across 50+ languages, suitable for YouTubers, podcasters, and content creators. Users can sign up to receive 5,000 free credits and start generating speech without needing a credit card. The platform provides a variety of voice options, including American, British, Australian, Spanish, French, and more, each with distinct characteristics for different use cases.

OmniVoice is a free, open-source AI voice generator that supports 646 languages. It converts text to natural-sounding speech, clones voices from a short audio sample (zero-shot Voice Cloning), or creates a voice from a text description alone (Voice Design). Developed by the k2-fsa research team and trained on 581,000 hours of open-source speech data. OmniVoice is released under Apache 2.0, free for personal and commercial use.

SpeechifyAI is a research lab advancing speech synthesis, voice cloning, and emotional expression. Its flagship model, Simba 3.2, is ranked #1 on Artificial Analysis TTS leaderboard, offering sub-100ms latency and low cost. The platform provides a single API for streaming, voice cloning, emotion control, and multilingual synthesis across 30+ locales.
Related categories
What is text-to-speech AI?
Text-to-speech AI turns written text into natural-sounding spoken audio using neural voice models, going well beyond the robotic voices of older systems. It can narrate videos, articles, and audiobooks, voice characters, or read content aloud for accessibility, in many languages and voices.
Core features to look for
- Natural neural voices across many languages
- Control over voice, accent, tone, speed, and emphasis
- Voice cloning from a short sample (some tools)
- SSML or an editor for pauses and pronunciation
- MP3/WAV export and an API for apps
- Free tier with character or usage limits
Who uses text-to-speech AI, and how
01
Video & podcast voiceover
Narrate YouTube videos, ads, and explainers without recording your own voice.
02
Audiobooks & articles
Turn long text into listenable audio for creators and readers.
03
Accessibility & reading
Read content aloud for users who prefer or need audio.
04
Apps & phone systems
Add spoken output to products, assistants, and IVR via API.
How does text-to-speech AI work?
Modern text-to-speech uses neural models trained on recorded human speech to predict how text should sound — its rhythm, intonation, and pronunciation — then synthesizes the audio waveform. Controls like SSML, or cloning from a voice sample, shape the accent, emotion, and pacing of the result.