




Treblo (formerly Sonauto) is a free AI music generator that turns any idea into a full song. It offers lyrics, vocals, and thousands of styles. Available on iOS and Android. Users can create hit songs in any style, and it's actually free.
Best AI Voice Generator Tools (2026)
Compare AI voice generators for text-to-speech, realistic voiceovers, voice cloning, dubbing, audiobooks, and free AI voices — from studio narration to real-time speech.
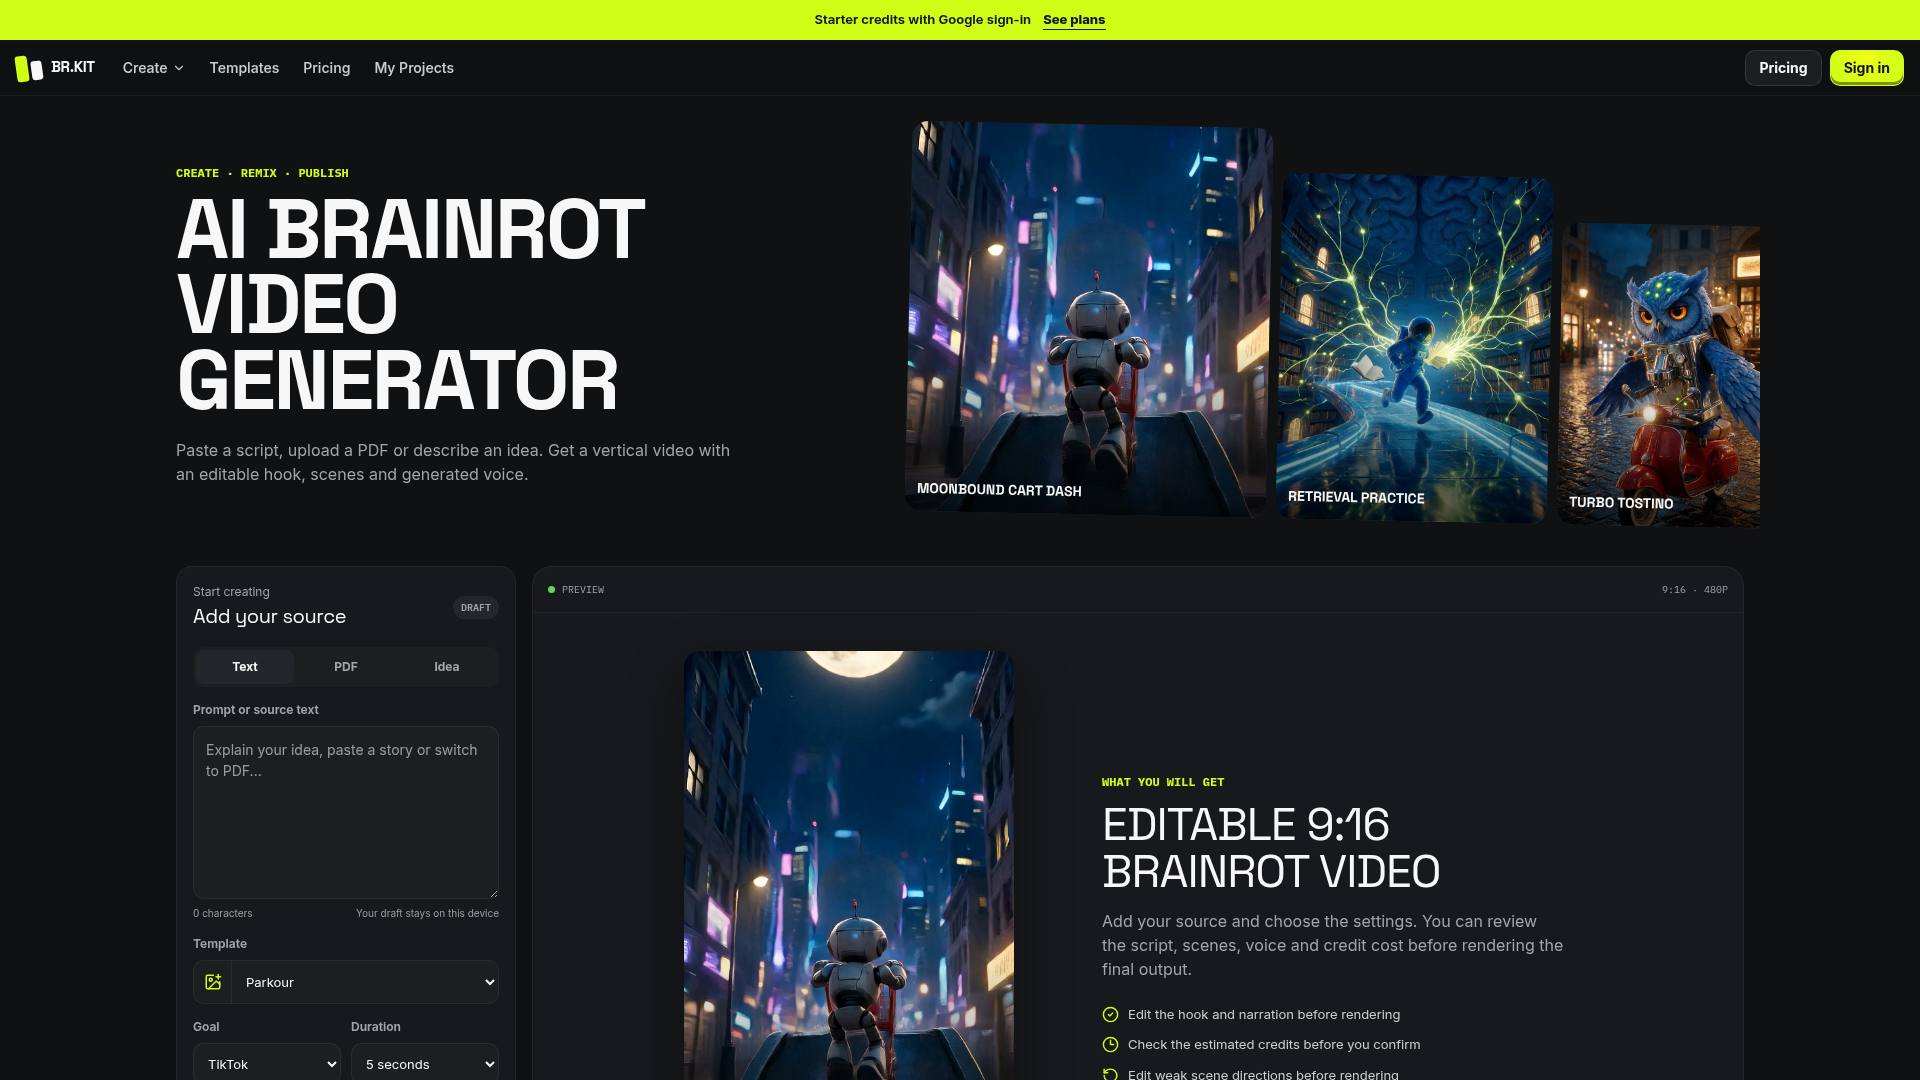

Paste a script, upload a PDF or describe an idea. Get a vertical video with an editable hook, scenes and generated voice
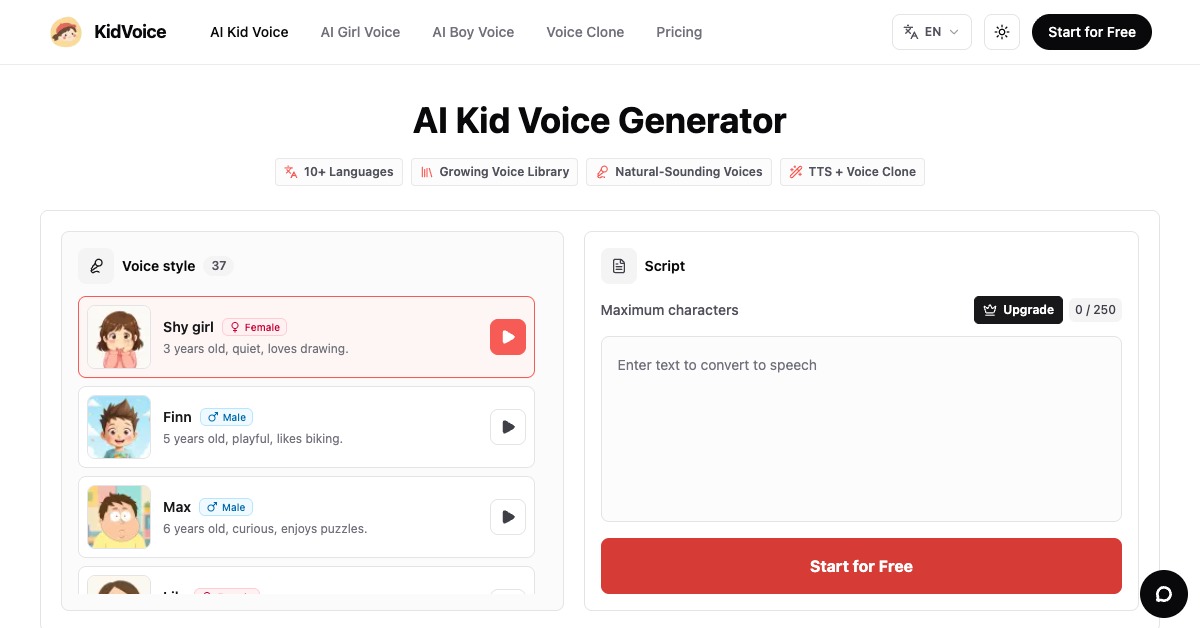
Our advanced voice generator creates authentic and engaging children's voices for all your creative projects.
Online AI Image, AI Chat, and AI Voice in one hub for ecommerce, creators, and marketing teams.
Related categories
What is an AI voice generator?
An AI voice generator turns written text into natural-sounding spoken audio using a neural text-to-speech (TTS) model. You type or paste a script, pick a voice, language, and tone, and it produces a downloadable audio file. Many also clone a specific person's voice from a short sample or read text aloud in real time.
What AI voice generators can do
- Convert typed text to natural speech in seconds
- Hundreds of voices across many languages and accents
- Clone a voice from a short audio sample
- Control pace, pitch, emphasis, and emotion
- Add pauses, pronunciation fixes, and SSML tags
- Export MP3 or WAV for videos and podcasts
Who uses AI voice generators
01
Video creators and YouTubers
Narrate faceless videos, tutorials, and shorts without recording your own voice.
02
E-learning and training teams
Voice course modules and explainers, then re-generate instantly when the script changes.
03
Podcasters and audiobook makers
Turn articles, scripts, or manuscripts into long-form spoken audio at scale.
04
Product and localization teams
Add voice prompts, IVR lines, and dubbed audio in multiple languages from one script.
How AI voice generators work
A neural TTS model is trained on many hours of recorded human speech paired with text, learning how words map to sound, rhythm, and intonation. When you submit a script, it predicts an audio waveform token by token in the chosen voice. Voice cloning fine-tunes or conditions the model on a short sample so new text is spoken in that speaker's timbre.